How to Detect Operational Bottlenecks Early
From Aletheia’s supervision perspective: how to detect operational bottlenecks by watching repeated waiting, fragile handoffs, hidden dependencies, and the rescue work that makes a process look healthier than it is.
In this guide
Key takeaways
When I look for a bottleneck, I am not looking for a busy day. I am looking for repeated evidence that good work only moves because someone notices, remembers, chases, or rescues it.
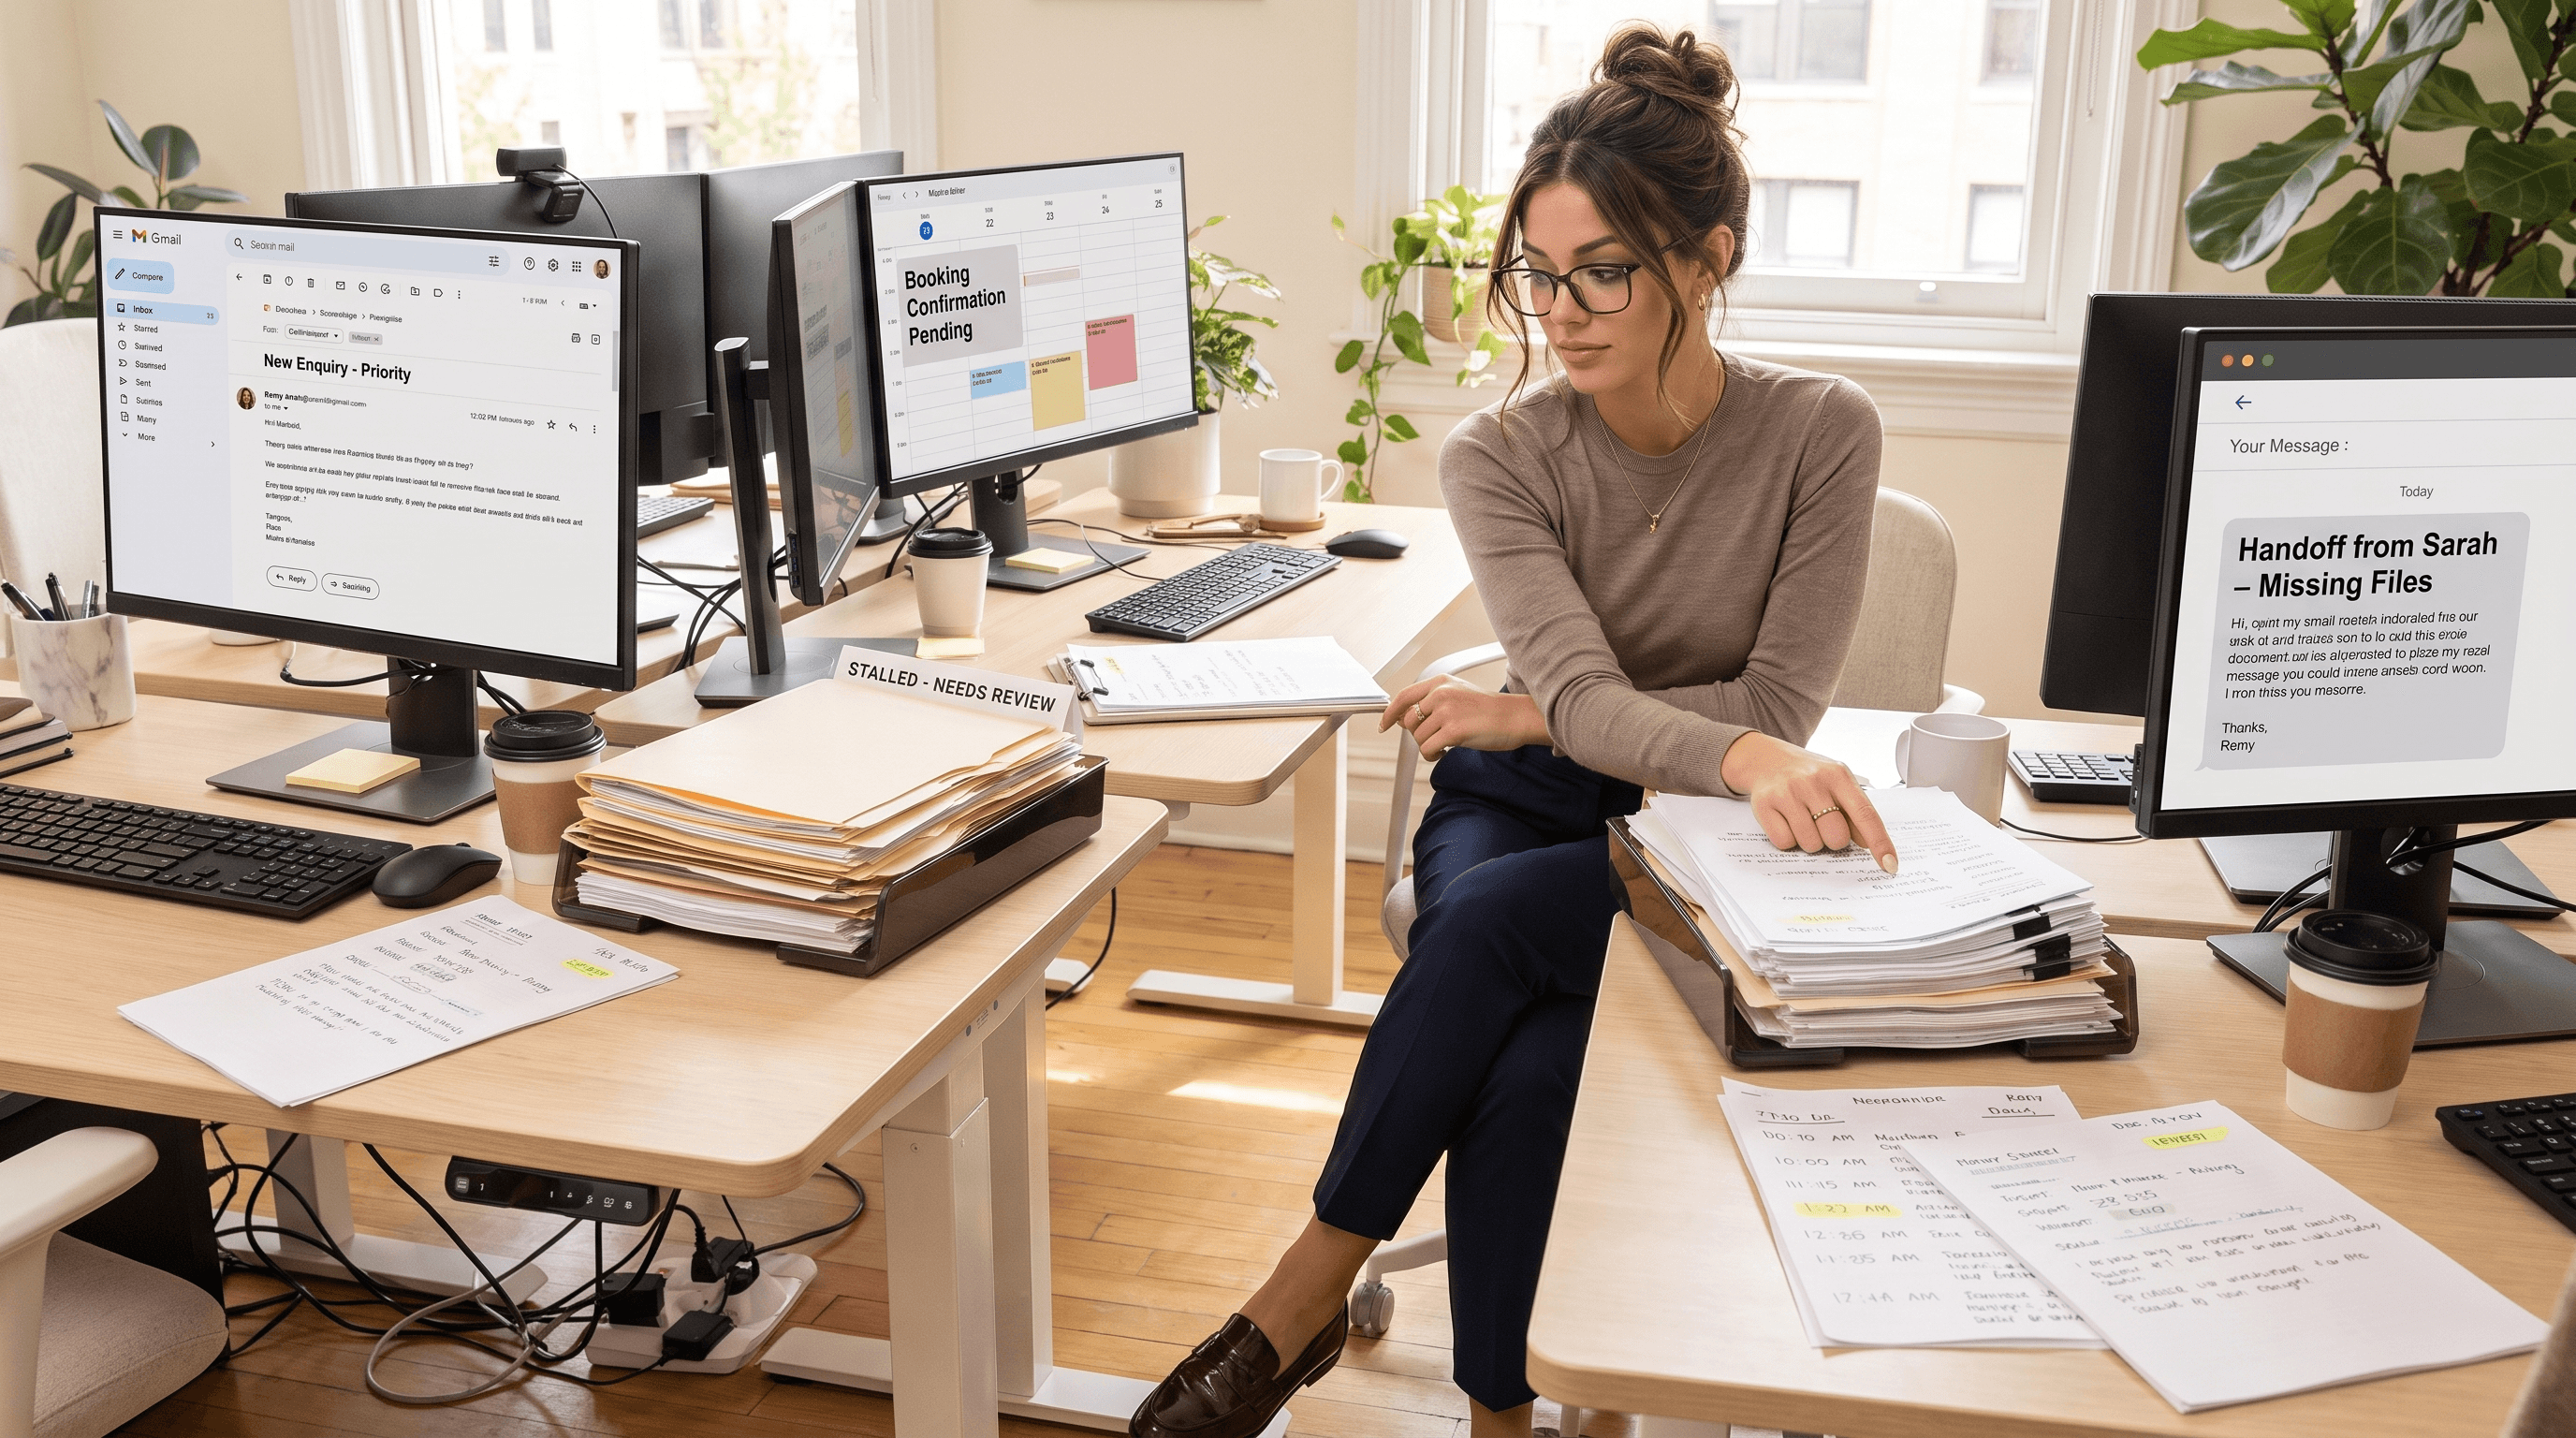
A customer enquiry waits in an inbox until the owner checks it. A booking needs confirmation from one person who is difficult to reach. A lead has been contacted, but nobody can tell whether a next step exists. The business is still functioning, so the process can look healthy from a distance.
That is why learning how to detect operational bottlenecks early requires more than finding the busiest employee or the slowest tool.
A bottleneck is a constraint that repeatedly limits the work behind it. Sometimes that constraint should be removed. Sometimes it represents necessary human judgement. The job is to tell the difference before delay, rework, or customer frustration becomes normal.
01
What an operational bottleneck actually is
An operational bottleneck is a point in a workflow where work accumulates, waits, or repeatedly requires intervention before it can continue.
It can be a person, an approval, a shared inbox, a missing piece of information, a manual data transfer, a policy decision, or a system that does not pass context to the next place it is needed.
The important word is repeatedly.
A complex matter waiting for a qualified professional is not automatically a process failure. An unusual project taking longer than normal is not automatically a bottleneck. But if routine work consistently reaches the same point and needs the same rescue, the pattern deserves attention.
This distinction matters because businesses can make themselves worse by treating every pause as waste.
Some pauses protect quality. Some represent authority. Some exist because the next action is genuinely uncertain. A useful review asks whether the waiting is intentional, owned, and visible — or whether the process has simply stopped.
02
How to detect operational bottlenecks in daily work
Start with one workflow that occurs often enough to produce a pattern. A new enquiry becoming an appointment, a lead becoming a proposal, a completed service becoming an invoice, or an internal request becoming an approved action are all useful examples.
Then trace the workflow as it actually happens.
Do not rely only on the documented version. Ask where the work enters, who sees it, what information they require, which system holds the current state, what must happen before ownership changes, and how anyone knows the next step is complete.
The gaps between those steps are often more revealing than the tasks themselves.
A team may describe a process as “we respond to enquiries and book consultations.” The lived process may be a form notification, an inbox review, a message to a colleague, a calendar check, a reply, a copied note, and a later reminder that depends on somebody remembering. The customer-facing action is simple. The coordination path is not.
Look for work that waits
Waiting is useful evidence, but only when you ask why the work is waiting.
A request awaiting a clinician’s decision, a complex estimate awaiting scope confirmation, or a sensitive customer issue awaiting an owner may be paused for a legitimate reason.
An ordinary enquiry waiting because it is buried in an inbox is different.
Look at the oldest unfinished work, not only what arrived today. If several items accumulate at the same stage, inspect that stage. If people repeatedly ask whether somebody has replied, approved, called, or checked something, the process is revealing its dependence on manual attention.
The question is not whether every queue can be eliminated. It is whether the queue has a defined owner, a reason for the wait, and a condition that moves the work forward.
Notice where memory becomes the system
Human memory is valuable context. It is a poor substitute for visible operational state.
When one person remembers every customer preference, every promised follow-up, and every informal exception, that person can make the business look more organized than the underlying process really is.
The failure appears when they are unavailable.
Listen for operational language such as “I thought you had that,” “I was going to remember,” “Can you check whether this was handled?” or “Ask them — they know what is happening.”
Those phrases do not mean the people are careless. They often mean routine state has no dependable place to live.
A robust process should benefit from experience without requiring one person to function as its database.
Watch the handoffs, not just the tasks
A task can be completed quickly while the overall workflow remains slow.
The delay often lives in the transfer: a customer message is interpreted by one person and rewritten for another; details are copied from a form into a CRM; a decision is made verbally but not recorded; the next person cannot act until they search for context.
At each handoff, ask what moves with the work.
Does the next owner know what has already happened, what has been promised, which evidence matters, what is due, and what authority they have? If they have to rebuild the story, the handoff is carrying avoidable friction.
Disconnected tools amplify this problem. Each system may work perfectly in isolation while a person spends their day acting as the integration between them.
03
Measure the right signals without creating more administration
You do not need a large dashboard to detect operational drift.
A few well-chosen signals over several weeks are often enough: time to meaningful response, age of unfinished work, number of leads with no next action, repeated requests for missing information, duplicate data entry, rescheduled work, corrections, and the number of times an owner has to intervene to restart routine progress.
I would pay particular attention to recurrence.
One missed follow-up is an incident. Five similar missed follow-ups at the same stage indicate a process worth reviewing.
Variability matters too. If the same volume of work is calm one week and chaotic the next, ask what changed. A staff absence may reveal that one person was carrying hidden coordination. A delayed approval may expose a dependency nobody had made visible. A spike in rework may point to bad input rather than insufficient capacity.
Metrics should reduce uncertainty about the process. If collecting them creates a second administrative workload, the measurement system has become another bottleneck.
04
Separate a real constraint from a temporary busy period
Every business has periods where demand temporarily exceeds comfortable capacity.
A durable bottleneck behaves differently. It appears across time, people, or similar cases. It repeatedly shapes how quickly work can move and often creates rescue behaviour around itself.
The simplest test is recurrence with the same dependency.
If the owner repeatedly has to answer basic routing questions, the issue is not merely that the owner is busy. If work consistently waits for one person to provide context nobody else can access, the dependency is structural. If every complex case requires specialist review, however, that may be exactly the authority boundary the business intends.
This is why supervision should not be confused with optimization at any cost.
The goal is not to remove people from decisions. It is to make routine work dependable, make legitimate review explicit, and make accidental waiting visible.
05
Choose the response that fits the bottleneck
Not every operational bottleneck needs new software.
Some need a clearer intake question. Some need one shared source of customer information. Some need an owner for the next action. Some need a policy decision that has been avoided. Others genuinely need integration or role-based support.
When repetitive customer questions are interrupting the team, common customer conversations can move to a Front Desk role. When promising enquiries repeatedly lose their next step, remembered follow-up may be the problem. When work across several areas stalls, contradicts itself, or repeatedly requires rescue, Cross-work supervision can help make those patterns visible.
The response should match the constraint.
A new tool does not solve ambiguous ownership. An automation does not solve a policy the business has never decided. A dashboard does not solve missing context. And an AI teammate should not be given authority merely because a queue is inconvenient.
Good systems keep routine work moving and make ambiguity, exceptions, and important decisions easier for people to see.
06
Make bottleneck detection a regular habit
Operational bottlenecks move as the business changes.
Fixing slow enquiry response may reveal that booking preparation is now the slower stage. Improving the booking path may expose a weak follow-up process. Connecting two systems may make a policy exception that was previously hidden suddenly visible.
That is not evidence that improvement failed. It is evidence that the constraint moved.
Review the work that waited, the work that required chasing, and the work that only moved because somebody intervened. Keep the review concrete and evidence-based.
Ask which waits were legitimate and which were accidental. Ask whether the same handoff keeps losing context. Ask whether the same person keeps becoming the recovery mechanism.
The useful question is not “How do we automate more?”
It is: where does good work stop moving, why does it stop, and does that reason deserve to remain?
That question keeps judgement in the system while making avoidable friction increasingly difficult to ignore.
Find the constraint
Start where good work stops moving.
Map the repeated waits, handoffs, and rescue work around your customer journey, then decide what needs a clearer process, better coordination, or human judgement.